Author: anthonygarces

  • When a Template Beats Custom Software: The Honest Version

    When a Template Beats Custom Software: The Honest Version

    An agency publishing when not to hire it; four jobs where the cheaper tool wins
    Do not hire us. For these four jobs.

    You are expecting this article to end in a pitch. It will not. Anito builds custom software for a living, and this page exists to name the four situations where you should not buy it from us, because a buyer who knows where custom pays is the only buyer worth quoting.

    There is also a number behind this: the industry itself split. CIO.com’s June 2026 analysis reports the two-decade habit of “buy software by default” eroding as AI tooling cuts build costs, with the advice landing on a split: buy for commodity workflows, build for the ones that differentiate you. The risk, they write, has shifted “from can we build it to can we govern what we build.” Gartner separately forecasts the low-code market (tools that build software with visual assembly instead of code) reaching $58.2 billion by 2029. The tools are not the enemy. Paying custom prices for a commodity job is the enemy, and it cuts both directions.

    The four cases where the cheaper tool wins

    • A standard online store. Products, cart, checkout, standard shipping. Established store platforms do this better and cheaper than a custom build, with payments, taxes, and security already handled. Custom earns back its price only when the selling rules themselves are yours (configurable industrial products, quote-based ordering, price lists that fight the platform’s model).
    • A brochure site whose job is to exist and be found. A good template on fast hosting, real text, real photos, and basic performance care gets you there for a fraction. You upgrade to custom when the site has to do work: intake, quoting, accounts, scheduling.
    • Commodity back office. Payroll, bookkeeping, email, standard documents. Buy. Nobody’s differentiation lives in payroll, and the compliance surface changes constantly. CIO.com’s split says exactly this: commodity workflows stay bought.
    • An internal tool for five people. Low-code tools are built for this and priced for this. Gartner’s forecast exists because that demand is real. The upgrade trigger is scale or surface: the tool starts touching customers, or the workaround list grows longer than the tool.
    Decision flow: write the workflow on one page; a named tool doing 80 percent verbatim means buy; otherwise custom fits; either way ask for the exclusions list
    The one-page decision. The no branch is the honest one.

    If a tool does your job verbatim, buy the tool. Anything else is paying custom prices to own a worse copy of something that already exists.

    Where custom earns its price

    The dividing line is not complexity. It is ownership of the workflow. When the way you intake, quote, dispatch, follow up, or manufacture is itself the competitive advantage, the off-the-shelf model becomes the ceiling: you bend your operation to match the tool, and the difference between you and your competitor (who bought the same tool) rounds to zero.

    That is the honest answer to “why custom”: not newer, not shinier. The software should match the workflow that makes you money, and the workflow should never be edited to fit a package.

    How we say this in practice

    Our own portfolio carries the labels. Milyon Digital is a live client website we designed and built custom (Next.js with a decoupled CMS), and you can open it today: the site does work a template could not, which is what made custom the right call. Our other projects are labeled demonstrations, not clients. And the honest-no page on our site lists the situations where we tell a visitor not to hire us, this article’s argument in first person.

    The check, whichever way you lean

    • Write the workflow on one page. If a tool you can name does 80% of it verbatim, the tool wins; budget the remaining 20% as accepted manual work before you call a developer.
    • Price both directions for three years. The template’s monthly fee compounds; the custom build’s cost is front-loaded. Run your real numbers, not a rule of thumb from either side.
    • Whichever you buy, ask for the exclusions list in writing. A price with no exclusions is an opening position, and this is true for a $40-a-month tool and a $40,000 build alike.

    If you wrote the one-page workflow and it did not match any tool verbatim, you are the buyer custom is for. Read our build versus buy guide for the full decision framework, look at what we build, and when you want the range and assumptions in writing, discuss your project. The reply will tell you what it depends on, and it will say so when the answer is a template.

    Common questions

    You are an agency publishing “do not hire an agency”. Why?

    Because a builder who cannot name when their product is wrong cannot be trusted on when it is right. The honest-no is the strongest page we keep: it costs us quotes, which is exactly why competitors who need those quotes cannot copy it. If your job fits a template, this page just saved you money, and that is the reputation we would rather build on.

    Can we start on a template and move to custom later?

    Often yes, and the migration cost depends on decisions made early, mostly about data: keep your customer, order, and product data clean and exportable from day one. What does not transfer well is workflow logic embedded in a no-code tool; document your business rules outside the tool so the next system inherits the rules, not just the records. Ask any builder (tool or custom) what the exit looks like before you buy, and the answer will tell you how the exit was priced.

    Is low-code the same as a template?

    Close enough for a buying decision, with one distinction: a template is a finished product you configure (a store theme, a site design); a low-code tool is a visual assembly kit for building small applications without code. Both win on standard needs and both hit the same ceiling: the moment your workflow stops matching what the assembly kit models. Gartner’s $58.2 billion forecast for 2029 says the kit market is real; the ceiling is equally real.

    How much does custom software cost, honestly?

    It depends on scope, which is why we publish how the number gets made instead of a single figure: scope first, price second, milestones rather than lump sums, and a written exclusions list with every quote. Ask any developer for the assumptions behind their range. A range with stated assumptions is checkable; a single number with none is a negotiation opening.
  • Nobody Signs Off on Their Own Work. That Is the QA Plan.

    Nobody Signs Off on Their Own Work. That Is the QA Plan.

    The work was signed off by the person who built it; that is the one check humans fail
    Signed off by the builder.

    The demo works. The developer who built it runs it, clicks through it, nods, and says it is done. You accept it. Three weeks later the invoice flow breaks on the one case nobody tried: two people editing the same record at once.

    Nothing malicious happened in that story and nobody was lazy. One human checked their own homework, which is the one check humans are bad at. The fix is not working harder. It is structural.

    The rule and why it works

    At Anito, nobody signs off on their own work. The person who accepts a feature is not the person who built it, and QA sits outside the build team entirely. The rule is cheap to state and does its work in a specific moment: the moment the builder’s certainty meets a second person’s fresh eyes.

    Fresh eyes find what certainty hides. The builder knows what the feature is supposed to do, so their clicks follow the happy path. A second person asks what the unhappy path looks like: two users at once, a network drop mid-save, a file with the wrong shape. Those are the cases that reach your customers, because they are the cases the happy path never meets.

    The happy path the builder checks, the unhappy paths where customers live, and the structural rule that nobody accepts their own work
    What certainty hides: the happy path never meets the cases that bite.

    What acceptance should look like

    The rule extends past QA to you, the payer:

    • You review working software, not reports. Working features land in a test environment (a private copy of the system) that your team opens themselves. If acceptance happens over screenshots, you are accepting a story about software, not software.
    • Findings are in writing. QA runs the agreed workflows and the failure cases, and writes down what broke. A written finding is checkable, debatable, and survives the project. “It feels solid” is none of those.
    • Acceptance has a written basis. You accept against the agreed scope and the written findings, so the sign-off is a documented decision, not a developer’s assurance with your name attached.
    • The open-items list ships with the acceptance. What is done, what is not, and what it will take. A handover without an honest still-open list is a handover with a surprise invoice inside it.

    Where the scars come from

    I ran the technical support team at Pantheon, the platform hosting large-scale sites, for four years. The tickets taught me which part of a failed launch bites first, and it is rarely the part people expect: the launch works, the demo worked, and the first real Tuesday breaks it, because Tuesday brings the concurrency, the bad data, and the user nobody scripted. That career is checkable; the lesson from it is on this page because it saves you the expensive version (this is the founder writing, and the career is on LinkedIn and the about page to be judged, not believed).

    The discipline shows up in what we publish, too. Our FMMS product (a facilities maintenance system) is a working demonstration with zero deployments, and we say that plainly, because a demonstration labeled as a demonstration is worth more than a claim dressed as a client. Every project on our portfolio carries its status for exactly this reason.

    The check

    • Ask any developer you are quoting with: “who signs off on the work, and did they build it?” A one-sentence structural answer means the practice exists. A pause means you just found your risk.
    • Ask: “can I see findings in writing from your last build?” Real QA produces documents the way construction produces dust.
    • Ask: “where do I log in to review work before accepting it?” You want a link you control, before invoice one, not after.
    • Ask: “what is still open after this invoice?” The builder who answers with a list is the one who knows the answer.

    Support and handover are where this rule pays out last: the written findings and the honest open-items list are what make leaving cheap, which is what makes staying meaningful. Our guide to when your developer disappears covers the version of this you get to do alone, and our process page shows the review and acceptance steps in order. If a current project has no second pair of eyes on it, discuss your project with us. We will tell you what a review pass should include, and you can hand that list to whoever you like, including someone else.

    Common questions

    Does a second reviewer slow the work down?

    It moves the slowness to where it is cheap. A review pass takes minutes to hours. The bug it catches takes days, arrives in production, and bills you twice: once to find it under pressure and once to rebuild the trust it spent. Teams that run outside QA ship at a comparable pace with fewer surprise invoices, and the surprises they do get are smaller.

    What does QA actually test, day to day?

    Two lists. The agreed workflows (the paths your business runs every day: order in, invoice out) and the failure cases nobody scripted: double submissions, missing fields, two users colliding, a network drop mid-save. The first list proves the system works. The second list proves it survives. A QA pass with only the first list is a demo with paperwork.

    What is a test environment, in plain words?

    A private copy of your real system, on its own address, where new work lands before customers can reach it. Your team clicks through it at their own pace. It differs from the live system in one way that matters: mistakes there cost nothing. Any build you pay for should hand you a login to one before the first acceptance.

    We already launched without any of this. Is it too late?

    No, and the honest sequence starts with a review pass over what is live: the workflows that make or lose money first. You get a written findings list, you fix by priority, and the structural rule starts applying from that day forward. Rescue work of that kind is a service we offer, and a second pair of eyes you can hire for a review alone, even when the building stays with someone else.

  • AI Wrote the Code. Who Checked It? (2026 Numbers)

    AI Wrote the Code. Who Checked It? (2026 Numbers)

    AI wrote the code; the question is who checked it before it shipped
    AI wrote it. Who checked it?

    Your developer demonstrates a feature that took “one afternoon with AI.” The price drops. The timeline shrinks. You sign. Six months later a payment goes out twice and nobody can explain the code that did it, because nobody ever read it.

    Nobody is lying to you in that story. That is what makes it dangerous.

    What the 2026 numbers actually say

    AI in software work is now universal, and the numbers are public. Google’s DORA report (about 5,000 technology professionals) found 90% use AI at work. Stack Overflow’s 2025 survey (49,000 developers) found 84% using or planning to use AI tools. The same survey measured something the pitch decks skip: 46% of developers distrust the accuracy of AI output, the first year distrust outweighed trust (survey.stackoverflow.co/2025/ai).

    DORA’s own finding is sharper still: AI adoption correlates with better throughput and worse delivery stability. Their phrase is the honest one: AI amplifies what is already there. A disciplined team ships faster with AI. A sloppy team ships slop faster, and the slop reaches your customers at machine speed.

    Even the feeling of speed is under investigation: a randomized trial (METR, 2025) measured experienced developers at 19% slower on their own mature codebases while they believed they were about 20% faster. One study, one narrow setting, worth reading before accepting a feeling as a forecast.

    The question nobody asks out loud

    Not “do you use AI?” Everyone does; asking it buys you nothing. The question is: what happens between AI writing code and that code reaching my customers?

    The answer you want has named layers: the machine checks that run before anything ships, the human who reviews what the machine cannot judge, and the rule about what is never allowed to act on its own. The answer you do not want is a smile and the word “iteratively.”

    Where we put the line

    Our rule, in use on every build: AI does the reading, sorting, extracting, and drafting. Plain automation (rules written once, checked, and safe to run twice) handles the rules, because rules do not hallucinate. A human approves anything that matters. Nothing auto-sends to a customer. Nothing commits a payment.

    Four layers between the AI and the customer: AI drafts, machine checks, human review by a different pair of eyes, then ship
    Four named layers. The answer you want names all of them.

    I paid for that rule the expensive way. Years ago I built a hosting panel and, riding the first wave of AI coding tools, let the machine run while I watched anime. The feature count climbed. So did the bugs, and I burned hours and tokens fixing what a day of structure would have prevented. Speed without governance gets expensive: the lesson arrived on my invoice, which is why it is a rule here and not a slogan (this story is the founder’s, and it is on the record so you can judge how we learned it).

    The governance also has a second line of defense: nobody at Anito signs off on their own work, and that includes work produced with AI. The person who accepts the output is never the person (or machine) who produced it.

    There is a quiet reason the earlier posts in this series keep returning to machine checks, and this is it: reviews scale only when the boring part is automated. A type contract and a gated build catch the shape mistakes and the broken checks before a human spends attention, so the reviewer’s judgment goes on the decision the machine cannot make: is this the right behavior, is this safe to ship, who does this touch. AI raised the volume of produced code. The answer is not more heroes reading everything. It is more of the work checked by machines and the remainder checked by a different human, in that order.

    The check, in four questions

    Put these to any developer quoting with AI in the pipeline, us included:

    • “Show me what happens between AI writing code and it reaching production.” You want a named pipeline, not a description of a mood.
    • “Who reviews AI output, and are they the person who prompted it?” The review should be a different pair of eyes.
    • “What can AI touch on its own?” The answer that keeps you safe: nothing that reaches a customer or moves money without a human.
    • “What tests would catch a wrong answer the AI was confident about?” Confidence is not correctness. Tests are.

    For the business-workflow version of this (reading documents, sorting mail, drafting replies with a human approving), see our safe AI automation checklist and our workflow and AI automation service. If a quote is riding on AI speed, discuss your project with us before you sign it. We will tell you what the quote should be able to answer, and the answers will tell you whether you need us.

    Common questions

    Should we forbid AI in projects we pay for?

    You would be paying 2026 prices for a 2019 workflow, and most teams would hide the AI anyway. The productive demand is governance: named checks before shipping, review by someone other than the person who prompted the AI, and a hard rule that nothing customer-facing or money-moving acts on its own. Ask for those three in writing; the teams that have them will say so in one sentence.

    What is “bounded AI”?

    AI confined to the parts of a workflow where being wrong is recoverable and visible: reading, sorting, extracting, drafting. The parts where being wrong costs money (sending to a customer, committing a payment, deleting a record) stay with plain rules and a human approval step. The phrase on this site carries a specific commitment: AI assists, and a human approves anything that matters.

    Does AI-written code need different tests?

    It needs the same tests taken more seriously. Machine-written code tends to look correct and fail at the edges, so the tests that matter are the ones that poke boundaries: empty input, double submission, missing files. A type contract and a named test pipeline catch the majority of it before shipping, which is why the previous posts in this series keep returning to those two.

    How do we know a developer actually has governance and is not just claiming it?

    Ask for the artifact, not the assurance: the checklist document, a sample review record, the test names. Teams with governance produce it in minutes because it already exists. The ones without it will offer a promise, and a promise is the thing this entire blog is built to price correctly.

  • We Measured Three Ways to Read Big Data. The Lesson Saves Money.

    We Measured Three Ways to Read Big Data. The Lesson Saves Money.

    Demo speed and Tuesday speed are two different measurements
    The demo was warm. Your Tuesday is not.

    The demo was flawless. Ten million rows, instant search, no waiting. You bought it. Six weeks later your real data is in, and the same search takes long enough that staff have started avoiding the screen.

    Nothing was faked in that demo. That is the trap. The speed was real, on that machine, with that data, already warm. Demo speed and your-Tuesday speed are two different measurements, and almost nobody quotes both.

    We ran a set of experiments on data reading inside our own internal tooling (research infrastructure of ours, not a client project, and said plainly). The lesson generalizes to any system you buy or build, and it is the reason we ask the questions most demos never answer.

    The three ways software reads data

    When software needs facts from a big file or table, there are three doors:

    • Load it all. Pull the whole thing into memory (RAM, the fast working desk inside the machine) and search it there. Blazing fast while it fits. When the data outgrows the desk, the whole approach collapses at once.
    • Stream it. Read the file in ordered pieces, front to back, using memory the size of one piece. Works on any amount of data. Punishes anything that needs scattered, jump-around access.
    • Map it. Memory mapping (the technical name is mmap) asks the operating system to make the file pretend to be memory. The program touches it like an array, and the OS fetches pages from disk behind the scenes, only the pages actually touched. The desk never holds the whole file; the filing cabinet sends pages on demand.
    Three doors into a big file: load it all, stream it, map it; plus the trap where run two flies only because the page cache was warm
    Three doors, one trap: never mistake a warm cache for a fast disk.

    The interesting engineering is rarely picking one. Our experiments ran a hybrid: map the parts worth jumping around in, stream the parts read in order, and keep a switch that turns the mapping off entirely so the same workload runs both ways. That switch (the plain word is an ablation: disable the trick, measure the trick) is what separates measurement from marketing.

    The trap the experiment exists for

    Here is the failure that eats buyers: run the search once, it crawls. Run it again, it flies. Conclusion: the mapping works. Conclusion is wrong.

    The second run was fast because the operating system kept the pages in memory from the first run (that cache is called the page cache). The disk never got faster. The demo machine, warmed by rehearsal, was showing you its cache, not its speed. Our own working rule from these experiments is one line: never mistake a warm cache for a fast disk.

    The honest version of the experiment runs cold, on data bigger than memory, with the trick switched on and off, and reports both numbers. Anything less is a rehearsal.

    The failure path is the product

    The other lesson came from testing, not speed. Part of this work used sealed files (read-only files the operating system itself refuses to let anyone modify) so a bug could not corrupt data. One of our tests started failing intermittently: 173 failures in 400 runs. The file was never actually leaking. A nearby thread in the test was nudging a global counter the test counted on. The test was measuring the neighborhood, not the house.

    Rewritten to check the exact thing it claimed to check, the same test found zero leaks and stopped crying wolf. The business translation: a test that fails for the wrong reason trains everyone to ignore alarms, and an ignored alarm is how real failures ship. When you pay for a system, you are paying for the tests to be the kind that mean something on a bad day.

    What to ask, whatever you buy

    • “What happens when the data outgrows memory?” A system designed on load-it-all has a cliff. The answer names the design; the honest answer names the cliff.
    • “How was the speed claim measured?” You want to hear: cold start, data larger than memory, trick on and off. Anything else is a warm machine telling you a story.
    • “What does the system do when a file is missing halfway through?” Data work lives or dies on the failure path, and the failure path is testable in a demo if you ask before you sign.

    Read our guide on what a passing test actually proves, and if a speed demo is sitting in your inbox waiting for your signature, discuss your project with us first. We will tell you which questions to put to it, and the answers will tell you whether you need us at all.

    Common questions

    What is memory mapping (mmap), in one sentence?

    An arrangement where the operating system makes a file on disk pretend to be a section of memory, so the program reads it like a simple array while the OS quietly fetches only the pages actually touched. It trades the program’s memory budget for disk traffic, which is exactly why it shines for scattered reads on big files and disappoints when the workload does not match.

    Why would anyone still load everything into memory?

    Because while the data fits, nothing is faster: memory access beats every disk arrangement. Small reference datasets (a currency table, a product list) are better loaded. The design error is assuming this year’s data volume is the ceiling. Ask what the design does at ten times the data, and you will hear which door the system is actually built on.

    What is a page cache?

    Memory the operating system uses to keep recently read disk pages around, so the next read of the same page does not touch the disk at all. It is why the second run of anything is faster than the first. It is also why a rehearsed demo outruns a production Tuesday: the demo’s speed is partly the cache talking.

    Was this experiment done on client work?

    No. It is research on our own internal tooling, run to sharpen the judgment we use on client systems, and it is labeled that way on purpose. What client work proves is separate: Milyon Digital is our live client site, and our demonstrations are labeled demonstrations. We keep the two honest because a research claim dressed as a client result is the exact fraud this blog exists to prevent.

  • What Deployment Should Mean for a Business Owner

    What Deployment Should Mean for a Business Owner

    A deploy is reversible: the way back is measured in minutes
    The deploy, and the way back.

    Your developer says “we’ll deploy it tonight.” You say yes. Then your site is down at 9 a.m. and the same developer says the word “rollback” like it is someone else’s job.

    Deployment (the moment new code replaces old code where customers can reach it) is the most under-priced risk in small business software. Not because deployments are usually bad. Because the ones that go wrong go wrong in public, and the difference between a bad afternoon and a lost week is decided before the deploy, by questions nobody asked.

    What a real pipeline has

    A pipeline is the road code travels from a developer’s keyboard to your customers. A real one has four checkpoints:

    • Automated checks before shipping. Machine-run tests and validations that block the release when they fail, no override by mood. Our own site’s rule is written in its public repository: lint, typecheck, test, build, all green or nothing ships (github.com/Anito-Systems-Solution/anito-main-web, AGENTS.md). The list is short and the discipline is the point.
    • A test environment you open yourself. A private copy of the site where you click the new feature before any customer can. Not screenshots. Not a developer’s screen share. A link you control.
    • A rollback that is measured in minutes. Putting yesterday’s version back, rehearsed, not improvised. If nobody knows how long a rollback takes, the answer is “as long as the outage lasts.”
    • Keys held in the right name. Hosting, repository, accounts. Yours, from day one. An agency that holds your keys owns your exit price.
    Pipeline stations: code changes, automated checks, test environment, live, with a rollback arc back to the previous version
    Named checkpoints and a way back. Red stops the train.

    Containers, since the quote will mention them

    The word you will hear in every deploy conversation is container. The plain version: the application and everything it needs to run get sealed into one box with its own fittings, and the box runs the same on a laptop, a test server, or production. Two things that buy you as the payer. The “it worked on the developer’s machine” conversation mostly dies, because the machine travels with the app. And rollback turns mechanical: yesterday’s box still exists, so going back is a switch, not a rebuild. Our own site ships this way, and the box recipes sit in the public repository next to the code they run. When a quote mentions containers, ask the only question that matters about them: who builds the box, and where is yesterday’s box kept?

    What 2025 and 2026 proved

    This is not theory. The year’s incidents wrote the checklist in public.

    The “Shai-Hulud” attack compromised more than 500 npm packages (the shared code libraries modern software is assembled from) and harvested credentials; a US government alert followed with the mitigations, and the first one is pinning your dependencies so a poisoned update cannot walk in (CISA alert, September 2025). A second wave in August 2026 hit more than 440 packages with over two billion combined downloads (Sygnia). Two waves in a year means “what code libraries does my software pull in, and are they pinned?” is a board-level question now, not a developer detail.

    Then the platforms themselves: Cloudflare’s global outage in November 2025 took down a long list of household names for over five hours, and the company’s own postmortem traced it to a configuration file and a permissions change, not a hacker. Weeks earlier, AWS’s biggest region had its worst outage in years. The internet’s biggest platforms failed on process, not machinery. If they are not immune, your answer is not “pick the safe platform.” It is “know your rollback and your exposure before the day.”

    The four questions

    • “What happens if a deploy goes wrong at Friday, 5 p.m.?” You want the rollback story, with a number of minutes in it.
    • “What runs before code ships, and can it block a release?” You want named checks, and you want to hear that a red check stops the train.
    • “Where do I click to see the new feature before my customers do?” You want a test environment link, and you want it in your name.
    • “Whose name are the repository, hosting, and accounts in?” The answer to this one is in your contract now, not in the handover later.

    Deploy discipline is also why we publish a ownership checklist to settle before invoice one: the deploy questions are exit questions wearing work clothes. If a current build has you uneasy, our process page shows what we put in writing before anything ships. To put your project against this checklist, discuss your project with us.

    Common questions

    How often should deployments happen?

    Small and often beats big and rare, because a small change that breaks something is found in minutes and rolled back in minutes. A three-month release is a three-month backlog of untested-together changes deploying at once. The rhythm we use on our own site is: gated changes shipped as they are ready, each one small enough to read and reverse.

    What is a rollback, exactly?

    Putting the previous version back so the business keeps running while the problem is investigated. A real rollback is rehearsed and measured in minutes, because the old version still exists and switching to it is mechanical. If a developer has to “figure out” a rollback while your checkout is down, that improvisation is the outage.

    Do these questions matter if we use a big hosting platform?

    They matter more. Cloudflare’s November 2025 outage and AWS’s October 2025 outage were platform-wide, traced to process and configuration, and no customer of either could do anything about them mid-incident. Your controls are the ones on your side of the fence: what you ship, how fast you can reverse it, and whether your own dependencies are pinned.

    What is dependency pinning, in plain words?

    Fixing the exact version of every shared code library your software uses, instead of floating on “whatever the latest is.” The Shai-Hulud attack moved through packages by publishing poisoned new versions; pinned projects did not catch it because they never asked for the new version automatically. It is the software equivalent of refusing packages you did not order.

  • How Real Systems Handle a Business’s Many Data Sources

    How Real Systems Handle a Business’s Many Data Sources

    Five sources, one truth: every copy knows where its master is
    Five sources, one truth.

    Count the places your business’s facts live tonight. The website form dumps into an inbox. The chat app holds decisions. Invoices live in the accounting tool. The real order list is a spreadsheet two people maintain. The delivery photos are on phones. Five sources, five logins, no rule for what happens when they disagree.

    Nothing is broken about any one of them. The cost is in between: the retyping, the checking, the “which one is right” that eats an hour here and an afternoon there. Multiply that by every week of the year and the number stops being small.

    Five sources feed one source of truth; two systems both claiming to be the master is the failure mode
    One master per fact. Two masters is how a Tuesday disappears.

    What a built system does differently

    Custom software that handles many data sources is not magic and it is not one big program that owns everything. It is three disciplines:

    • One source of truth per fact. A customer’s phone number lives in exactly one system, and everything else asks that system. Copies exist for convenience, but each copy knows where its master is. Most data pain in a small business is two systems both believing they are the master.
    • Movement that is safe to run twice. The job that copies new orders into the invoice system will sometimes run twice (a retry after a network hiccup, a manual re-run). A safe job detects that it already moved order 4,182 and skips it. The technical word is idempotent, and the plain test is: run it twice, check nothing doubled.
    • A record of what arrived when. When a number looks wrong, the log (the timestamped list of what each movement did) answers “when did this change” in minutes instead of an afternoon of guesswork.

    Two systems, one number, no rule: that is how a Tuesday disappears. The disciplines above are what remove the Tuesday.

    The experiment you can see in public

    This site runs the pattern on itself, at a size you can inspect. Its content lives in two places: a CMS (the writing and storage system on its own server) and a set of built-in copies that ship with the site itself. The site reads the CMS, falls back to the built-in copies when the CMS is unreachable, and no page goes down either way. The source is public (github.com/Anito-Systems-Solution/anito-main-web), so the fallback is a thing you can read rather than a claim you must believe.

    That is the small version of the discipline your business version needs: every reader knows its master, every reader survives its master being unavailable, and nothing important depends on two systems agreeing by luck.

    Where integration actually bites

    The hard part is never the copy step. It is the edges:

    • The same customer, spelled three ways. Matching records across systems (the same human in the form tool and the invoice tool) is the real work. Ask any developer how they will match, and what happens to a mismatch.
    • The tool with no door. Some systems have no way to read or write programmatically (no API, the term for a machine-to-machine door). The honest answers are manual export on a schedule, or replacing that tool. A developer who promises direct sync into a closed tool is promising the one thing it cannot do.
    • Backfill. Moving yesterday’s history into the new system, cleaned. It is a project inside the project, and it deserves its own line in the quote.

    Run the check yourself

    • List your systems and pick your most important number (open orders, unpaid invoices, booked jobs). Write which system is the master of that number. If two systems both feel like the master, that is your first finding.
    • Ask any developer you are quoting with: “if this job runs twice, what happens?” The ones who build real movements have a one-sentence answer and a test for it.
    • Ask: “which of our tools have APIs and which do not?” A straight answer with a plan for the closed ones is worth more than any diagram.

    If that list found something, you are looking at integration work, and it is most of what we build. Systems and API integration is where the mechanics above become working software. To talk about your specific tangle, discuss your project, or read why tools keep creating admin first. Bring the two-systems-one-number finding if you found it; it is the best brief you can hand any developer.

    Common questions

    Should we not just buy one big tool that does everything?

    For standard workflows, often yes, and we will tell you so. The moment to build is when your workflow outgrows what the tools model: your quoting has rules the tool cannot express, or your dispatch works in a way the tool fights. One tool covering 80% verbatim beats a custom build; the remaining 20% that carries your specific workflow is where custom earns its price.

    What is an API, in one sentence?

    A machine-to-machine door into a system, so software can read and write it without a human clicking through the interface. Tools with good APIs can be connected directly. Tools without one need scheduled exports, a workaround, or replacement, and any honest quote says which of the three your tool gets.

    How long does connecting our systems take?

    The movement itself is days, not months. The honest drivers of the timeline are the edges: matching customers across systems, backfilling history, and the tools without APIs. A quote that prices only the copy step and ignores the edges is a quote that will grow. Ask for the edges to be named, even as exclusions.

    Where does AI fit into integration?

    In the reading and matching, with a human checking: reading unstructured documents, suggesting matches between misspelled customer records, drafting the exception report. The rules themselves stay plain automation, because rules do not hallucinate. An AI step that writes directly into your invoice system with no human review is a bet you did not agree to place.

  • TypeScript: The Contract That Outlives Your Developer

    TypeScript: The Contract That Outlives Your Developer

    A machine-checked contract outlives any single developer
    The contract, written into the code.

    A developer leaves. Six months later someone asks for “the same report but with a totals row.” The change touches a field name, and that field name appears in eleven places nobody remembers. The old developer is gone, the list of places lives in their head, and your small change starts with an archaeology project.

    TypeScript exists to delete that archaeology. It became the most-used language on GitHub in August 2025, ahead of JavaScript and Python, growing 66% in a year (GitHub, Octoverse 2025). Here is what that actually buys a business owner, in plain words.

    A type contract, explained without jargon

    TypeScript is JavaScript with a written contract on every piece of data: this field is a date, that one is money, this one must exist, that one is optional. Before the code runs, a compiler (a machine checker, not a person) reads the contract and the code together and lists every place they disagree.

    Rename a field under a type contract and the compiler prints every file that mentions it. All of them. In seconds. Nobody has to remember anything, because the list is not in a head, it is in the build.

    With a type contract the compiler lists every place a rename breaks; hand search can miss a file
    Search is hope. A typed contract is a list.

    Search is hope. A typed contract is a list. Untyped code lets a bad rename sail through until a customer finds it, because nothing forces the eleventh place to admit it exists. The contract turns “I think we got them all” into a machine-checked sentence.

    The experiment we run on ourselves

    We apply the same idea past the code. Our site’s source (public: github.com/Anito-Systems-Solution/anito-main-web) carries machine checks that most sites do not bother with: a test that fails the build if rendered copy uses British spellings (the brand is US English by rule), and a test that fails if banned or previously fabricated names ever appear in copy again. The rules are the owner’s; the enforcement is the machine’s.

    That is the whole philosophy in one build: any rule a person has to remember will be forgotten on a Friday. A rule the machine checks survives every Friday. The type contract is that philosophy applied to your data, which is the part of the system your money actually flows through.

    Why the trend matters to your quote

    Stack Overflow’s 2025 survey (49,000 developers) measured TypeScript at 48.8% among professional developers. Nearly half the professional world can read it. That number is your hiring pool, your replacement options, and your exit plan, all measured instead of promised.

    It also changes what your maintenance costs. A change that a compiler checks cannot half-land: either the build passes or it lists what is broken. Fewer surprises in production means fewer emergency invoices, and the invoices that do come are for new work, not for rediscovering what the last developer already knew.

    What typed does not mean

    An honest limit, before anyone sells types as a guarantee: the contract proves the data has the right shape. It does not prove the business rule is correct. A field can hold a perfectly formatted number that is still the wrong number, which is why typed code still needs the tests and the outside QA pass described elsewhere in this series. Types delete one class of failure (shape mistakes, the renamed field, the missing value) so the human attention left over goes to the failures that need judgment. That is the trade, stated plainly: machine checks for shapes, human checks for meaning, and neither pretends to do the other’s job.

    What to ask

    Put this to any developer you are quoting with, us included:

    • “Is the code typed? If a field name changes, what tells you every place that breaks?” The answer you want is one word: the compiler. The answer you do not want is a person’s name.
    • “What machine checks run before code ships?” Typed or not, every build should have a list, and the developer should be able to name it without opening a laptop.
    • “Could another team take this over in a year?” Typed contracts are the cheapest handover insurance that exists, because the code documents itself at the exact spots where handovers go wrong.

    A template or a no-code tool for a standard store needs none of this, and if that is your job, buy the tool. The contract matters when the software carries your specific workflow, the one nobody else has. If you are weighing which side of that line your project sits on, discuss your project with us, or read our guide on the build versus buy decision. The answer sometimes is “do not hire anyone,” and we will say so.

    Common questions

    Is TypeScript a different language my team cannot hire for?

    It is JavaScript with contracts added, so any JavaScript developer already speaks most of it, and Stack Overflow’s 2025 survey measured it at 48.8% usage among professional developers. It is now the most-used language on GitHub. The hiring pool is large and growing, which is exactly why it lowers your risk instead of raising it.

    Does the type contract slow development down?

    It moves time from production surprises to writing time, which is the cheaper place to spend it. Writing contracts adds a margin to the first weeks. It repays on the first change that touches shared data, and on every handover after that, because the compiler catches the breakage class that otherwise reaches customers. For a small brochure site the margin may not repay; for a system carrying your workflow it does, quickly.

    Can I add TypeScript to existing code later?

    Yes, in slices: newest and riskiest code first, oldest code as it gets touched anyway. A full retrofit of a large old system is a project with a real price, and it is fair to ask any developer proposing one for the slices-first plan and the exclusions. If nobody proposes slices, ask why not.

    What does this have to do with AI-generated code?

    A contract is also the cheapest safety net for machine-written code. AI assistants produce code fast and confidently, and the compiler checks every line of it against the contract before it ships, the same as it does for human-written lines. Typed code plus automated checks is how teams get the speed without inheriting the errors.

  • A Next.js Speed Experiment Anyone Can Run on Us

    A Next.js Speed Experiment Anyone Can Run on Us

    Pre-built pages and a rebuild timer: visitors never wait for the machinery
    Speed, measured in public.

    Your site feels fast on your phone because your phone has visited it a hundred times. Your customers arrive cold, on a train, on a three-year-old phone, mid-checkout. Speed for them is a different number entirely, and that number has a revenue line under it.

    So we ran the experiment on ourselves first. Our own site is the test subject, its source code is public, and you can check every claim on this page in about ten minutes without asking our permission.

    What we changed

    A Next.js site (Next.js is the framework our site and our client work are built on) can serve pages two ways: build each page fresh for every visitor, or build it once ahead of time and hand out the finished page. Fresh-for-every-visitor is flexible and slow under load. Built-ahead is fast everywhere and risks going stale.

    The middle path is what we shipped. Each page is built ahead of time and handed out finished, and the parts that change get rebuilt on a timer: at most every 300 seconds, five minutes. The setting lives in one line per page, revalidate = 300, in our public repository (github.com/Anito-Systems-Solution/anito-main-web). A visitor never waits for the machinery. The machinery updates itself while nobody is looking.

    The experiment that matters more: unplug the CMS

    Our content lives in a separate CMS (the admin system where articles get written and stored, like a newsroom database) on its own server. The obvious failure mode: that server goes down, and every page that reads from it goes down with it.

    So we built the reads to degrade instead of die. Every time the site reads from the CMS, the read can fall back to a copy built into the site itself. Unplug the CMS and the site stays up: same pages, same articles, same links. The source code shows the fallback, and we test it by doing exactly that.

    If the CMS is unreachable the site serves built-in copies; no page goes down
    Every read has a second door. Designed to fail to a copy, not to zero.

    The site surviving its own CMS being unreachable is worth more to a business than any speed score, because the outage you get warned about costs you a bad afternoon, and the one that silently eats your checkout costs you customers you never counted.

    Why this pays out to you

    Two moves here, and both transfer to any build you pay for:

    • Finished pages beat fresh pages. When a developer proposes building every page on every visit “so content is always current”, ask what a five-minute rebuild timer would cost instead. Usually nothing.
    • Degrade, do not die. Any system that reads from another system should answer the question: what happens to my revenue pages when that other system is down? If the answer is a shrug, the shrug is the finding.

    The same pattern runs on Milyon Digital, the client site we designed and built with a decoupled CMS, and it is the reason we did not have to think hard about the answer for our own site: the pattern was already proven on work a customer can open and click through right now (milyondigital.com).

    What this does not fix

    Honest limits: pre-built pages do not fix a heavy image habit, a pile of third-party tracking scripts, or a theme that loads a design framework to render a paragraph. Those slow a page no matter how it is delivered, which is why a speed score reads as a list of fixes, never a single switch. When we test our own pages we read the score’s detail list, because the detail is where the work items live. A developer who quotes “performance optimization” as a line item without naming what is on the list is quoting a mood. The list is the deliverable; the score is the receipt.

    Run the check yourself

    Ten minutes, no permission needed:

    • Go to pagespeed.web.dev and test our site (anito.ai). Then test the portfolio page of any developer you are quoting with: their own site is their shop window. Look at their score, not their claims.
    • Ask any developer: “if the CMS goes down, what do visitors see?” A specific answer means they have thought about it. A pause means they have not.
    • Ask: “how long after I publish does the change appear, and what runs in between?” Our answer is five minutes, and the line of code is public.

    If that list made you want a second opinion on a build you are weighing, discuss your project with us. You will get a straight answer, including the answer that you do not need us yet.

    Common questions

    Does the five-minute rebuild mean my published changes take five minutes to appear?

    Up to five minutes for pages served from the pre-built copy, and the interval exists so a change never forces a visitor to wait for a fresh build. For most business content that delay is invisible. If a page truly cannot wait (a price change during a promotion, for example), that page gets a shorter timer or an on-publish trigger, and that is a per-page decision worth making deliberately.

    Is a separate CMS not just another thing that can break?

    It is another thing, which is exactly why the fallback exists. The alternative is editing pages in code, which puts publishing in the hands of whoever has developer access. Separating where content lives from how it renders keeps publishing with your team, and the fallback keeps the site alive when the content server has a bad day. Two systems with a designed relationship beat one system with a single point of failure.

    What speed number should I actually care about?

    The ones measured on a cold device on a mobile connection: Largest Contentful Paint (how long until the main content appears) under about 2.5 seconds, and Interaction to Next Paint (how fast the page responds when tapped) under about 200 milliseconds. PageSpeed Insights reports both. Care with lab scores produced on warm machines; the cold number is the one your customers get.

  • What Is a Full Stack Application? A 2026 Owner’s Guide

    What Is a Full Stack Application? A 2026 Owner’s Guide

    The four layers of a full stack application, from what customers see to how it reaches the world
    One system, four layers: interface, work, data, delivery.

    You asked three developers for a quote. Two of them wrote “full stack application” on it. Neither explained what it means, and one spelled it differently in two places.

    Here is what the term actually covers. It is not a product and it is not a price band. It describes everything a piece of software touches, and once you can see the layers, quotes stop being three private languages and start being comparable.

    The four layers, in plain words

    A full stack application is software where one team builds across all of these layers:

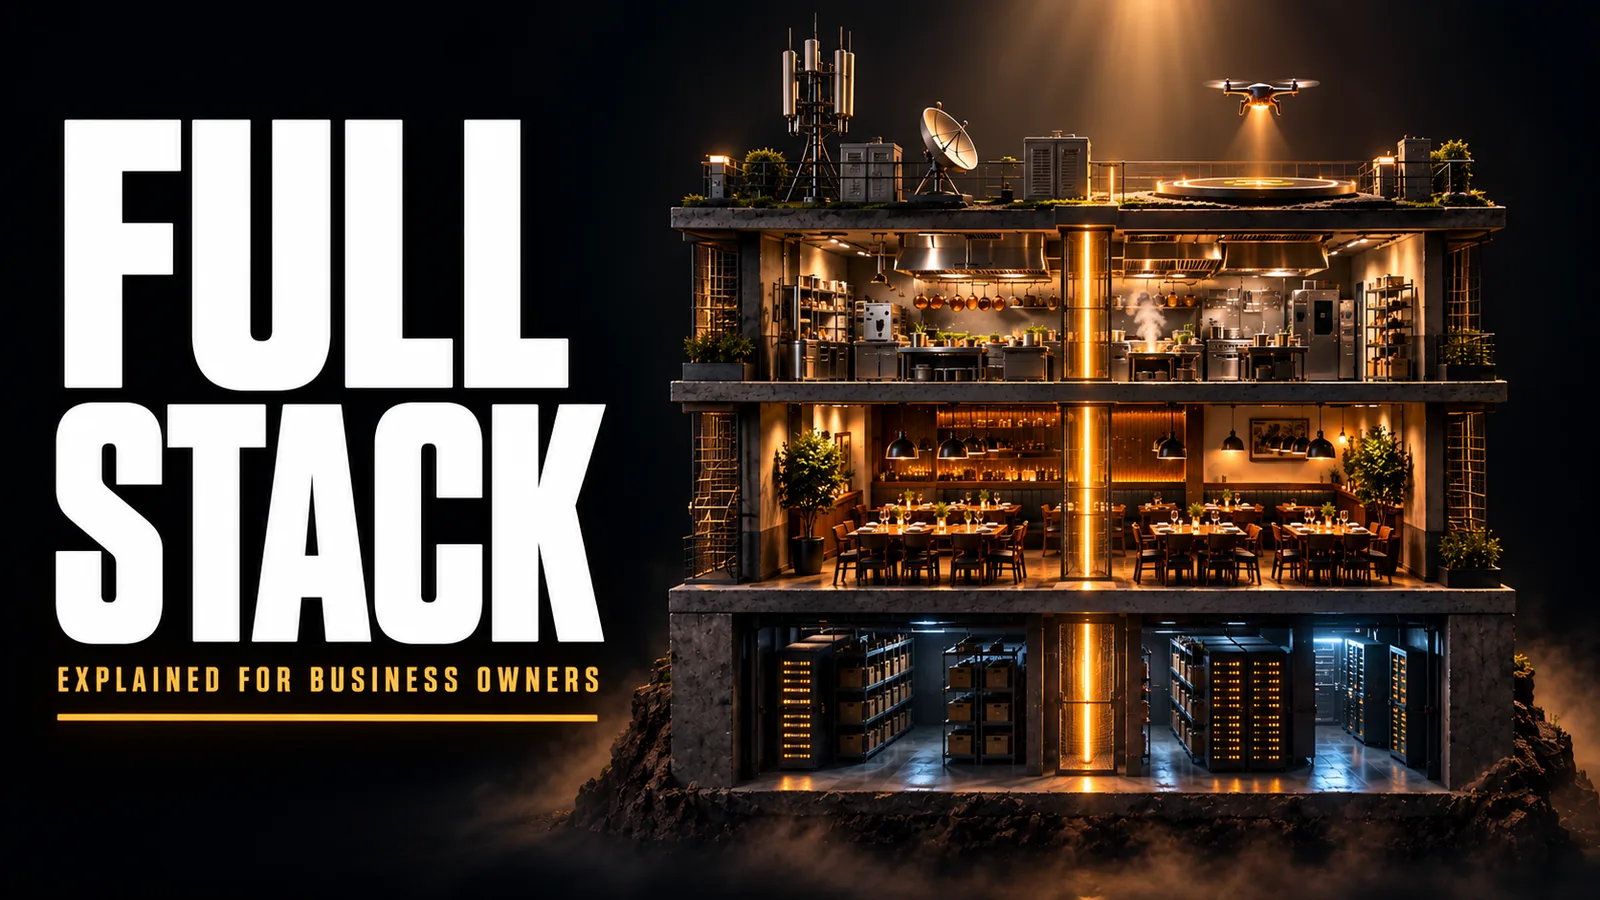
    • What people see (the frontend): the pages, buttons, and forms in a browser or on a phone. The dining room of the restaurant.
    • What does the work (the backend): the part customers never see. It takes a submitted order, checks it, and acts on it. The kitchen.
    • Where the data lives (the database): orders, customers, invoices. The storeroom, with a log of who took what and when.
    • How it reaches the world (deployment): the servers, the releases, the backups. How the food actually gets to the table while it is hot.
    One team accountable across all four layers: what people see, what does the work, where data lives, how it reaches the world
    Four layers, one accountable team. Gaps between layers are where work gets retyped.

    “Full stack” means one team is accountable for all four. When the person who built the button is not the person who manages the storeroom, gaps open between them. Gaps between systems are where work gets retyped.

    What the 2026 numbers say

    You do not need to take any developer’s word for what the standard stack is. It is measured, every year, in public.

    GitHub’s Octoverse report found TypeScript overtook every other language on the platform in August 2025, growing 66% in a year (GitHub, Octoverse 2025). TypeScript is JavaScript with a type contract written into it: mistakes in how data is handled get caught by a machine check instead of by your customers.

    The Stack Overflow survey (49,000 developers, 2025) measured what they use: Node.js, the JavaScript runtime that runs outside the browser, at 48.7%. React, the library behind a large share of the interfaces you touch, at 44.7%. Next.js, the framework that builds on React, at 20.8% (Stack Overflow Developer Survey 2025).

    The stack also moves on a schedule you can plan around, which matters when you are signing anything multi-year. Next.js 16 shipped in October 2025 with a rewritten compiler that cut build times several-fold and support for the newest React release (nextjs.org). The names stay the same; the versions roll; the team that tracks them is showing you a habit, and the habit is what you are buying.

    The boring stack won. Next.js, React, TypeScript, Node. That is good news for a buyer, for one reason: hireable. The most-used tools have the largest hiring pools, the longest documentation trails, and the most people who can take over when the original developer moves on. Choosing them is not fashion. It is exit planning.

    Three questions that test a quote

    Any developer who works on this stack daily answers these in one sentence each. Ask them:

    • “Which versions do you build on, and which ones still get security updates?” Node.js publishes a support schedule; the current long-term support release is version 24 (nodejs.org). “We use the latest” is not an answer. A version number is.
    • “What runs before code ships?” The automated checks (the machine-run tests that gate every release) have names. A team that has them names them in seconds.
    • “Who owns the repository from day one?” The repository is where your code lives. If the answer contains the word “eventually”, that is your exit price being decided in advance.

    What this does not mean

    None of this says every business needs a custom application. A standard online store, or a brochure site that exists to be found, is served well by a template at a fraction of the price. Custom earns its price where the workflow is yours: the intake, the quoting, the dispatch, the follow-up chain that no off-the-shelf tool matches, because nobody else works the way you work.

    The point of knowing the stack is narrower and more useful. You can hear the difference between a developer who builds on it daily and one quoting it because the word sells.

    We build on this stack daily. Our own site runs on it, and its source code is public, so you can read how it is put together (github.com/Anito-Systems-Solution/anito-main-web). If you are weighing quotes and want a straight answer about what the words on them mean, discuss your project with us. You will get a plain reply about what we would do, what it depends on, and whether you need us at all.

    Common questions

    Is “full stack” the same as “full service”?

    No. Full stack describes the technical layers one team builds across: interface, logic, data, deployment. Full service is a business claim about everything around the build, like design, copy, and support. Ask which layers the team personally builds and which they subcontract. Both models work, but the quote should say which one you are buying.

    Do I need a full stack application if I only need a website?

    Often no. A site whose job is to be found and to look right is served well by a template or a lean build, and it costs less. The full stack enters when the site has to do work: take orders, check stock, talk to your invoicing, hand tasks to staff. Name the work first; the stack follows from it.

    Which stack should I ask for by name?

    Ask for names, then ask why. Next.js, React, TypeScript, and Node form the most measured, most hireable combination in 2026, and they are a sound default for custom web work. What matters more is that the developer can say why those fit your job, and what they would use instead if something fit better. A developer with no “instead” is reading from a menu.

    Our current system is older technology. Does that change the answer?

    It changes the conversation, not the questions. Older systems raise the cost of the move and the value of an exit plan. Ask any quoting developer how they would run the old and new systems side by side during the change, and what happens to your history. Those answers are worth more than the framework name.

  • The Gate: Where an Engine Stops and Asks You

    An industrial conveyor stopped at a lowered barrier arm, with a hand hovering above a large green button.
    It carried the work this far on its own. This part is deliberately yours.

    Every worry about letting software run your operations comes down to the same sentence, whether or not anybody says it out loud.

    What if it does something stupid, fast, and nobody notices until it has done it four hundred times?

    That is a reasonable fear and it deserves a real answer rather than reassurance. The answer is a specific piece of design called the gate, and where you put yours is the most important decision in the whole build.

    What a gate actually is

    A gate is a point where the work stops, on purpose, and waits for a person.

    Not a notification. Not a log entry you could read later. A hard stop: nothing proceeds until somebody decides. The work sits there, visible, with everything already prepared — the document read, the fields extracted, the reply drafted, the numbers assembled — and a person makes the call.

    The important half is what happens either side of it. Before the gate, everything is done for you. At the gate, nothing happens without you. Not a compromise between automation and control; both, in the right places.

    Where gates belong

    Four categories. If any step touches one of these, that step gets a gate, and it is worth being unbending about it.

    • Money leaving. Payments, refunds, credit notes, anything that reduces what you are owed. No exceptions worth making here.
    • Anything a customer sees. A message, a quote, an invoice, a status update. The system drafts it. A person sends it.
    • Permissions and access. Who can log in, who can see what, who is added or removed. Quiet failures here are the expensive kind.
    • Anything irreversible. Deletions, cancellations, submissions to somebody else’s system that cannot be recalled.

    Everything else is a candidate for running on its own — reading, sorting, matching, calculating, drafting, moving, recording. Those are all reversible and all boring, which is exactly the definition of work that should not need you.

    The two ways gates go wrong

    Too few, and you have built something that can be wrong at scale. That is the fear at the top of this piece and it is a real failure mode. The tell in a proposal is that everything is described as fully automatic, with no screen where a person appears.

    Too many, and you have built a form that emails you. This is the more common failure and nobody warns you about it. Every step needs a click, so the work still moves at the speed of somebody’s attention. Six weeks later the approvals get rubber-stamped without being read, which is worse than no gate at all — now there is a record showing a human approved something nobody looked at.

    Which gives you the test that matters: a decision nobody has ever said no to is not a gate. It is a delay wearing a tie. Look at your existing approvals in whatever systems you already run and ask how many have ever been rejected. The ones that never have are ceremony, and they are training everybody to click yes without reading.

    What has to be on the screen

    A gate is only as good as what the person sees, and this is where most implementations are thin. When work stops for you, your screen needs four things.

    • What it wants to do, in a sentence, in plain language.
    • What it based that on — the source document, the message, the record. One click away at most.
    • What it is unsure about, named specifically. “The total was hard to read” is useful. A confidence percentage on its own is not.
    • What happens if you say no, and where it goes then.

    If approving means clicking yes on a summary you cannot verify without opening three other systems, you do not have a gate. You have a rubber stamp with extra steps.

    Why I hold this line hard

    I build open-source tooling for governing AI agents in my own time. The core idea in it is that a piece of ordinary, inspectable code sits outside the model’s loop and judges the work by evidence and executable checks, never by how confident the model sounds. It is genuinely pre-release and its own README lists the gaps rather than hiding them.

    That design came out of getting it wrong first. I built a hosting control panel fast, with an AI agent doing the typing and anime on the second screen. It was working, until it was not — hours gone to bugs that should never have existed, the agent reporting success while the code kept failing. Better prompts did not fix it, because prompting was not the problem.

    Intelligence bolted onto a bad structure is not intelligence. It is faster chaos. The gate is the structure. It is the difference between a system that helps and one that is confidently wrong at a speed you cannot keep up with.

    Place your own gates

    • Take one process and list every step from arrival to finished.
    • Mark each step against the four categories. Money, customer-visible, permissions, irreversible.
    • Every marked step gets a gate. Everything unmarked is a candidate for running on its own.
    • Now count your gates. More than two or three in one process and you should ask which are ceremony.
    • For each one, write what your screen shows. If you cannot describe it, that gate is not designed yet.
    • Audit the approvals you already have. How many have ever been refused? Ceremony is worth removing, not automating.

    What to do next

    Take one process, mark every step against the four categories, and count your gates. If you end up with more than two or three, some of them are ceremony — and ceremony is worth deleting rather than building.

    Then audit the approvals you already have for how many were ever refused. If you want the rest of the machinery, the six parts covers where the gate sits among them.

    If you want the whole picture instead of one workflow: tell us what’s still manual. You get a map of every point where your business stops and waits for a person, what that costs you in hours, and which of those an engine would take over first. Free, yours to keep, and useful even if you never hire us — including on the days the honest answer is that you should not build anything yet.

    Common questions

    What if I’m away? Does everything just stop?

    That is a design decision to make deliberately rather than discover, and it should be written down before build. Each gate needs a named alternate, and some gates should have a time rule — hold for four hours, then escalate to a second person. What you should refuse is a gate that quietly proceeds on its own after a timeout, because that turns your safety mechanism into a delay with an automatic yes at the end.

    How is a gate different from the approval workflow our current system already has?

    Frequently it is not, and if yours already stops work and shows you what you need, you have a gate. The differences that matter are whether it holds the work rather than just notifying you, and whether the screen shows the evidence rather than a summary. A notification you can ignore while the process continues is not a gate, whatever it is called in the menu.

    Can the same system decide which items need a gate and which don’t?

    Yes, and that is exactly where it earns its keep — routing the routine ones through and stopping on the unusual ones. What matters is that the rule for what counts as unusual is one you can read and change, not something buried in a model’s judgement. If nobody can tell you why this item stopped and that one did not, the routing is not inspectable and you should treat it with suspicion.

    Doesn’t a human at every important step defeat the point of automating?

    Only if you think the point is removing people. The point is removing the carrying — the gathering, re-typing, checking and chasing between decisions. A process with three genuine decisions in it should have three human moments, not thirty, and the thirty is what you have today. You end up making the same calls with better information and none of the assembly.